생산자-소비자 문제
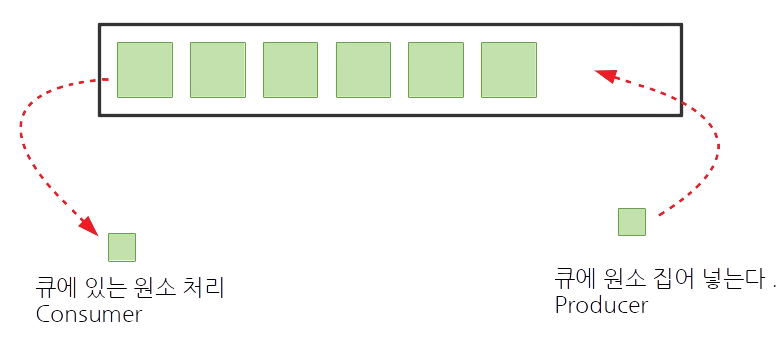
- 생산자-소비자 문제(Producer-Consumer Problem)은 운영체제나 멀티스레드 환경에서 여러 프로세스(또는 스레드)가 공유 버퍼를 통해 데이터를 주고 받을 때 발생하는 동기화 문제
- 한정 버퍼 문제(bounded-buffer problem)라고도 불린다.
- 두 가지의 주체가 존재
- 생산자(Producer) :
데이터를 만들어 공유 버퍼에 저장하는 역할 - 소비자(Consumer) :
공유 버퍼에서 데이터를 꺼내 사용하는 역할
- 생산자(Producer) :
- 위 두 주체가
동시에 실행되고, 버퍼의크기가 제한되어있고, 두 주체처리의 속도가 다를 때다음 문제들이 발생한다.- 생산자의 처리 속도가 더 빠를 때 - 버퍼가 가득찰 수 있음
-> 생산자는 데이터를 더 이상 넣을 수 없어야 한다. - 소비자의 처리 속도가 더 빠를 때 - 버퍼가 비어있을 수 있음
-> 소비자는 데이터를 더 이상 꺼낼 수 없어야 한다.
- 생산자의 처리 속도가 더 빠를 때 - 버퍼가 가득찰 수 있음
-> 따라서 생산자와 소비자는 동기화(Synchronization)를 통해 서로의 작업을 조율해야 한다.
발생하는 주요 문제
1. 임계 구역(Critical Section) 문제
- 생산자와 소비자가 동시에 버퍼에 접근할 수 있다면 데이터가 꼬이거나 손실될 수 있다.
-> 이를 막기 위해 상호 배제(Mutual Exclusion) 기법이 필요하다
2. 바쁜 대기(Busy Waiting) 문제
- 자원이 준비될 때까지 계속해서 조건을 확인하며 대기하는 현상 -> 효율적이지 못하다.
해결 방법
- 생산자-소비자 문제는 주로 세마포어(Semaphore), 뮤텍스(Mutex), 모니터(Monitor)등 동기화 도구를 사용해 해결한다
읽기용 세마포어:
버퍼에읽을 데이터가 있을 때만소비자가 접근하도록 제어쓰기용 세마포어:
버퍼에빈 공간이 있을 때만생산자가 접근하도록 제어뮤텍스:
생산자와 소비자가 동시에 버퍼에 접근하지 못하도록 상호 배제 구현
- 이러한 구조를 통해 생산자와 소비자는 다음과 같이 동작한다.
생산자:
버퍼에 빈 공간이 있으면 데이터를 넣고, 없으면 대기소비자:
버퍼에 데이터가 있으면 꺼내가고 없으면 대기
구현
#include <thread>
#include <iostream>
#include <vector>
#include <mutex>
#include<cstdio>
#include<queue>
#include <string>
#include <chrono>
using std::thread;
using std::vector;

void producer(std::queue<std::string>* downloaded_pages, std::mutex* m, int index)
{
	for (int i = 0; i < 5; i++)
	{
		//웹사이트 다운로드하는데 걸리는 시간
		//각 쓰레드별로 다운로드하는데 걸리는 시간다르다.
		std::this_thread::sleep_for(std::chrono::milliseconds(100 * index));
		std::string content = "웹사이트 : " + std::to_string(i) + "from thread{" + std::to_string(index) + ")\n";

		//데이터는 쓰레드에서 공유되므로 critical section에 넣어야 함
		m->lock();
		downloaded_pages->push(content);
		m->unlock();
	}
}
void consumer(std::queue<std::string>* downloaded_pages, std::mutex* m, int* num_processed)
{
	//전체 처리하는 페이지 개수가 5 * 5 =25개
	while (*num_processed < 25)
	{
		m->lock();
		//만일 현재 다운로드한 페이지가 없다면 다시 대기
		if (downloaded_pages->empty())
		{
			m->unlock();

			std::this_thread::sleep_for(std::chrono::milliseconds(10));
			continue;
		}

		//맨 앞페이지 읽어온 후 처리
		std::string content = downloaded_pages->front();
		downloaded_pages->pop();

		(*num_processed)++;
		m->unlock();

		//content 처리한다.
		std::cout << content;
		std::this_thread::sleep_for(std::chrono::milliseconds(80));
	}

}


int main()
{
	//현재 다운로드한 페이지들 리스트로, 아직 처리되지 않은 것들이다.
	std::queue<std::string> downloaded_pages;
	std::mutex m;

	std::vector<std::thread> producers;

	for (int i = 0; i < 5; i++)
	{
		producers.push_back(std::thread(producer, &downloaded_pages, &m, i + 1));
	}

	int num_processed = 0;
	std::vector<std::thread> consumers;

	for (int i = 0; i < 3; i++)
	{
		consumers.push_back(std::thread(consumer, &downloaded_pages, &m, &num_processed));
	}

	for (int i = 0; i < 5; i++)
		producers[i].join();
	for (int i = 0; i < 3; i++)
		consumers[i].join();
}
코딩 창고!